Jev: AI for everyday business decisions
TypeSafe AI's Jev turns text into structured decisions. What founders and small teams should know about its design, uses, speed, pricing, and limits.
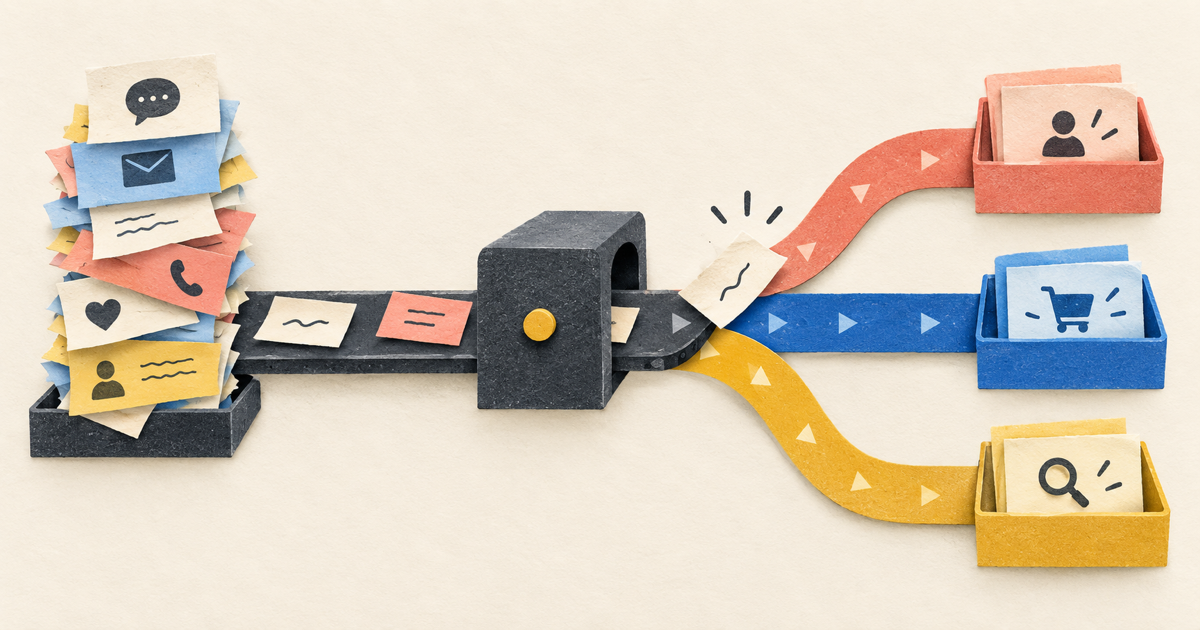
It's 10:00 am somewhere, and a customer has written in about an order. Is it a refund request, a delivery question, or something that needs a person right away?
For a small team, these tiny decisions pile up. AI can write a thoughtful reply, but the first useful step may be simpler: decide where the message goes, show how sure it is, and let the right workflow take over. That is the idea behind Jev, the first model from TypeSafe AI.
Why not just ask a chatbot?
Think about the AI tools we use most often: they give us sentences. That flexibility is useful when we want to brainstorm, draft, or explain something. Software, however, needs a dependable value to work with: “refund,” “delivery,” or “human review.” If a model replies in prose, another part of the system must interpret and check it before anything happens.
Jev is built for that decision step. Give it the relevant context, which TypeSafe calls the state, and a set of specific questions. It returns answers in formats defined in advance. A business still decides what happens next: route the ticket, request more information, or leave it for a teammate.
TypeSafe calls this family of models System One, borrowing the idea of fast, intuitive judgments. It is a way to add judgment to an existing process, one small decision at a time. It does not replace the rules, records, and people around that process.
Who’s behind Jev?
TypeSafe AI’s founders bring relevant research and engineering experience: Diogo Almeida worked on instruction following at OpenAI, Sasha Sheng was a research engineer at Meta/FAIR, and Erik Gafni builds production AI systems. Their background explains the focus on decisions inside software. Whether Jev fits your business depends on how well it handles your own recurring cases.
What does Jev actually give you?
You can ask Jev three kinds of question. A Choice picks from options you supply, such as sales, support, or billing. A Score rates something against levels you describe, such as low, medium, or high urgency. A Noul gives a number from zero to one for a yes-or-no question, such as “Does this customer ask for a refund?” You can ask several questions about the same state in one call.
For a Choice, Jev returns the selected option and a probability for each possible option. A Score does the same across the levels you defined. Both also include a confidence number that sums up how clearly one answer stands out. If “support” and “sales” look almost equally likely, that uncertainty is visible. A Noul returns only the probability that its yes-or-no statement is true; it has no separate confidence number. Your team can use those signals to route clear cases automatically and send close calls to a person.
Under the hood, TypeSafe says Jev uses a new model architecture, a parallel way of producing answers, and training it calls Reinforcement Learning for Calibrated Decisions. The practical goal is to make its probabilities useful for deciding when to act and when to pause. Its documentation recommends breaking a complicated judgment into smaller questions, then combining the answers with rules your team controls.
How would support routing work?
Suppose we want to sort an inbox into billing, delivery, and technical support queues. Here is a worked example using TypeSafe’s question types. The output numbers are illustrative, not results from a live Jev request.
The input
“Hi, I see two charges for order A-104. Could you check the second one and refund it if it’s a duplicate? The order arrived yesterday.”
Send that message as the state, along with the queue definitions. Billing handles charges and refund requests; delivery handles missing or late orders; technical support handles problems using the service; other catches anything outside those categories.
The questions
- Queue — Choice: “Which queue should handle the customer’s main request?” Options: billing, delivery, technical support, or other.
- Urgent — Noul: “Does the customer say the issue prevents them from using the service right now?”
The output
The fields our routing rule uses could look like this:
{
  "queue": {
    "choice": "billing",
    "probabilities": {
      "billing": 0.96,
      "delivery": 0.02,
      "technical_support": 0.01,
      "other": 0.01
    }
  },
  "urgent": { "noul": 0.03 }
}
The routing rule
For this example, route automatically only when the selected queue is not “other,” its probability is at least 0.90, and the urgency probability is at most 0.10. Send every remaining case to human review. This rule uses the selected option’s probability directly; it is different from the separate confidence statistic returned with a Choice.
The message passes both thresholds, so our code puts it in the billing queue. A close call with billing at 0.51 and technical support at 0.44 would go to a person. So would a ticket with an urgency probability of 0.65, even if its queue were clear. Routing the refund request does not approve a refund; billing still checks the payment records.
Those thresholds are starting assumptions for the example. TypeSafe’s guidance on uncertainty leaves the boundaries to your workflow. Test them against messages your team has already routed, then measure wrong assignments, missed urgent cases, and how much review work remains.
Where could a small team use it?
- Customer support: sort incoming requests by topic and urgency, while keeping unusual or uncertain cases with a person.
- Sales intake: route enquiries to the right service or teammate based on what the customer actually asks for.
- Operations: flag order notes, forms, or feedback that may need attention, before a human makes a consequential call.
- AI product checks: inspect a chatbot’s inputs or replies for specific issues and decide whether to show, review, or block them.
These are possible workflows, not claims that Jev comes with a finished help desk or sales system. Someone still has to connect it to your tools, define good categories, test the decisions, and decide where human review belongs. Jev currently takes text input, including structured text data; images, audio, and video need another step to turn them into usable text first.
Does Jev fit your workflow?
Jev is worth a trial when you already have a recurring text-based decision, stable categories, and a useful next step for each answer. An inbox that receives hundreds of similar requests gives you something concrete to evaluate: can it send enough tickets to the right queue to save time after human review and corrections?
If you mostly need replies drafted, documents explained, or help exploring an unfamiliar problem, the decision primitives alone do not deliver that work. If your support tool already routes tickets reliably, another service may add integration and maintenance without much benefit. And when a few keyword rules handle nearly every case, try those first.
Compare Jev with your current rules or model on the same labelled messages. Count correct routes, urgent tickets missed, the share sent for review, response time, and total running cost. A low token price matters less if someone must keep correcting the queue. For a small team, the strongest result is attention saved while preserving the decisions that need a person.
How fast is it, and what does it cost?
TypeSafe reports response times of roughly 70 to 500 milliseconds for its service. Its System One workflow comparisons produced headline figures of 193.6 times faster and 444.6 times cheaper than the models it compared. Those are company-run comparisons for this particular style of decision, and TypeSafe itself says the largest gains are likely at the high end of what teams will see in practice. Network location, the length of the input, and the shape of a workflow will matter.
| Model | Provider | Input | Output |
|---|---|---|---|
| GPT-6 Astra | OpenAI | $10.00 | $50.00 |
| Claude Fable 5.1 | Anthropic | $10.00 | $50.00 |
| Claude Opus 5 | Anthropic | $5.00 | $25.00 |
| GPT-5.6 Terra | OpenAI | $2.00 | $12.00 |
| Claude Sonnet 5 | Anthropic | $2.00 | $10.00 |
| Claude Haiku 4.5 | Anthropic | $1.00 | $5.00 |
| GPT-5.6 Luna | OpenAI | $0.20 | $1.20 |
| Jev | TypeSafe AI | $0.042 | Free |
Source: the Jev.Cost comparison on TypeSafe AI’s site, captured September 22, 2026. These are TypeSafe’s comparison figures; prices may change. We have omitted its GPT-5.6 Sol row because the source marks that price with an asterisk without explaining what it means.
The listed Jev price is $0.042 per million input tokens, or $42 per billion, with no charge for output tokens. Tokens are small pieces of the text you send, so the bill depends on how much context and how many questions each call contains. A request with 1,000 billed input tokens would be about $0.000042 at that rate, before any other costs of building or running the workflow. Pricing and access can change; Jev was introduced in early access.
Start with one repeat decision
If you run a small business, the most useful question may be: which repeat decision takes up attention every day, has a clear set of outcomes, and can safely wait for a person when the answer is uncertain? Start there. Measure whether the routing actually saves time and whether the mistakes are acceptable.
Jev makes an interesting bet: useful AI at work may often look less like another conversation and more like a quiet, well-defined decision inside a process we already understand.